

Word Count Program in Apache Spark using Spark DF | PySpark
In this blog, we will check on the various methods available to solve the word count program in Apache Spark using Spark DataFrame. We had already solved a same problem with solution build using Spark RDD. We used Map(), FlatMap() and reduceByKey() in Spark RDD method.
I will provide the link to our previous tutorial below, you can go ahead and read if you are interested in solution to word count problem using RDD.
Word Count in Apache Spark using Spark RDD

Problem:
Consider we have a text file for which we need to count the number of occurrences of each words. Use only Spark Dataframe to solve this quest. Sample text file used for this demo can be downloaded from the given link
Github: Sample textfile
Solution:
Video Solution with Explanation:

We will have couple of hands-on method to solve the Spark Word Count problem. Let us go through one by one.
Read the give file as Spark DataFrame:
We will use Spark text DatarameReader API. This will create a Spark DF with a column name value as shown below,
Code Snippet:
df=spark.read.text("dbfs:/FileStore/about_us.txt")
display(df)
out[]:

Method 1: Using GroupBy():
Code Snippet:
#import required pckg
from pyspark.sql.functions import explode,split,col

#Apply Split, Explode and groupBy to get count()
df_count=(
  df.withColumn('word', explode(split(col('value'), ' ')))
    .groupBy('word')
    .count()
    .sort('count', ascending=False)
)

#Display Output
df_count.display()
Out[]:

Method 2: Using Spark UDF():
Code Snippet:
Step 1 - Create Spark UDF:
We will pass the list as input to the function and return the count of each word.
#import required Datatypes
from pyspark.sql.types import FloatType, ArrayType, StringType

#UDF in PySpark
@udf(ArrayType(ArrayType(StringType())))
def count_words(a: list):
  word_set = set(a)
  # create your frequency dictionary
  freq = []
  # iterate through them, once per unique word.
  for word in word_set:
    freq.append([word,a.count(word)])

  return list(freq)
Step 2 - Apply the UDF to get Word Count:
#import required Functions
from pyspark.sql.functions import explode

#Apply UDF and get count of words in file
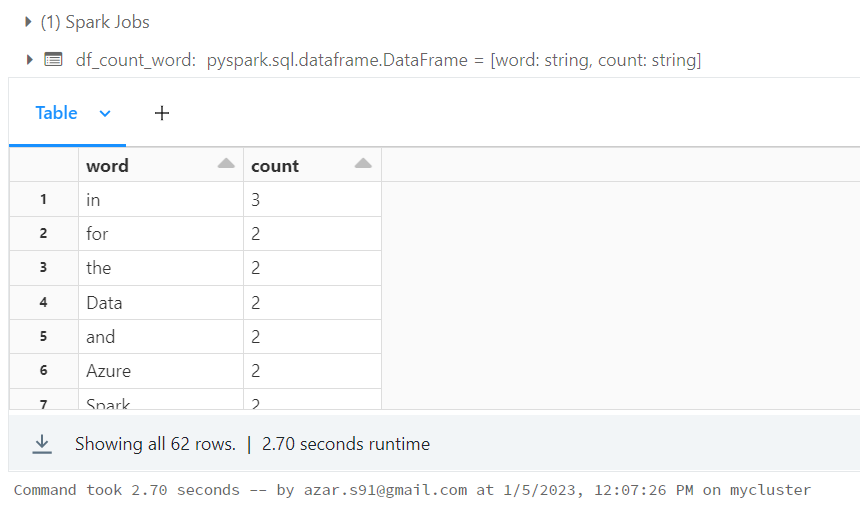
df_count_word=(
  df.withColumn('wordCount',explode(count_words(split(col('value'), ' '))))
 .withColumn('word',col("wordCount")[0])
 .withColumn('count',col("wordCount")[1])
 .drop("value","wordCount")
 .sort('count', ascending=False)
)

#display output
df_count_word.display()
Out[]:
Performance:
Both the methods discussed above gave same results, but when it comes to performance UDF performed slightly better than groupBy(). With Pandas Vectorized UDF, the performance can be further improved a lot. Try both the method and let me know your comments. Code we used can be accessed from the below give git link.
Happy Learning !!!



1 Comments
It'd be helpful if you can include how to clean the data also.
ReplyDelete